SCOREAgents & automation
Agent Evals Layering and Jev Scoring

Abdul Wasey@iabdul_wasey
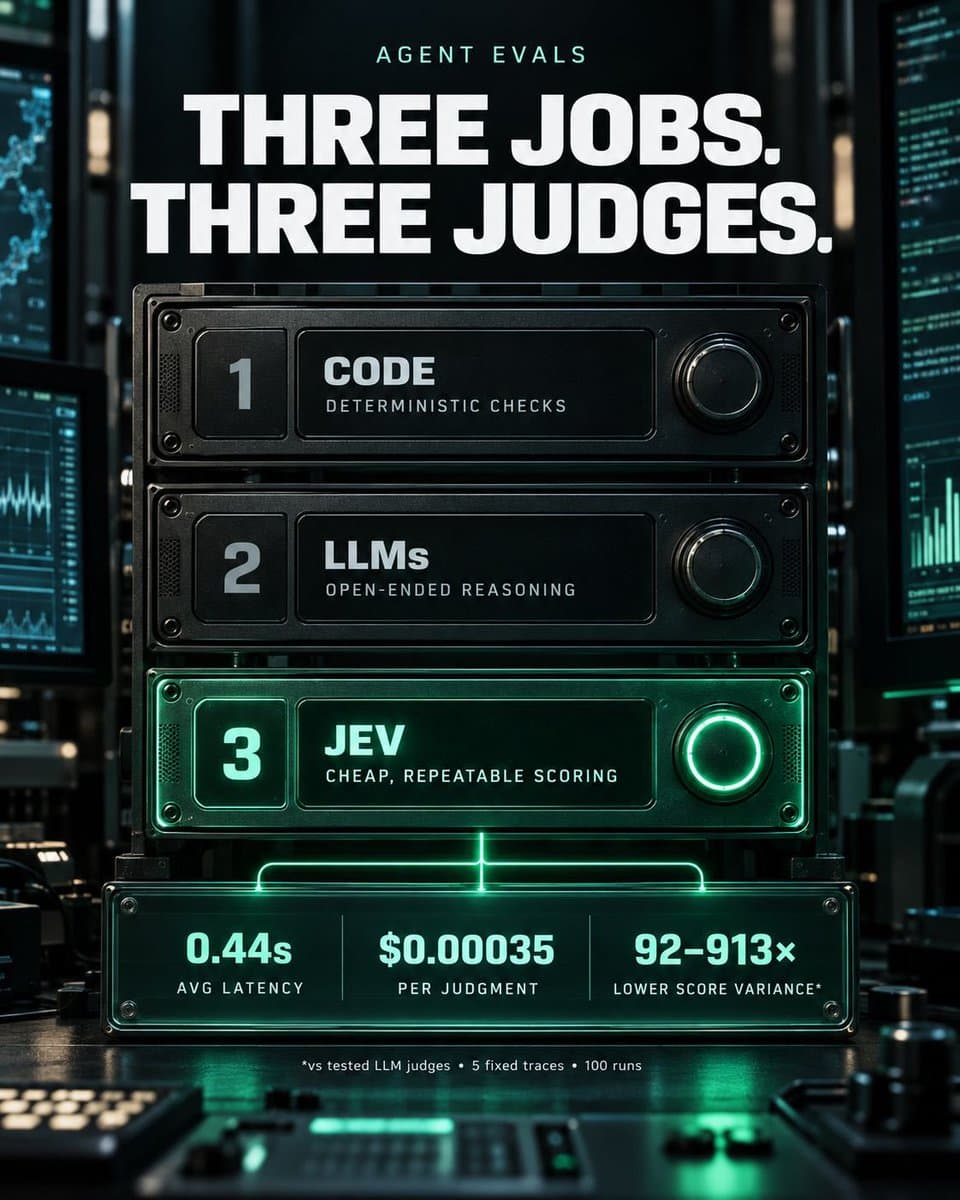
This project explores a three-layer architecture for agent evaluations, incorporating deterministic code, LLMs for reasoning, and decision models for repeatable scoring, with a specific focus on the performance of 'jev' for judgment.
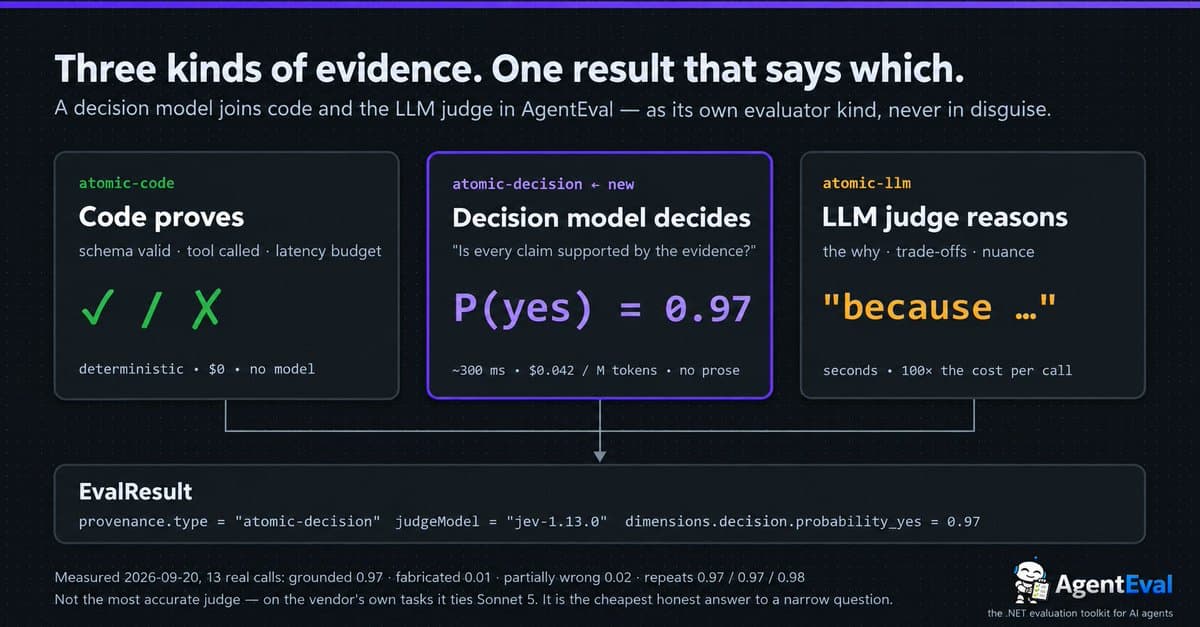
agent evals may be splitting into 3 layers:
- code for deterministic checks.
- LLMs for open-ended reasoning.
- decision models for cheap, repeatable scoring.
@LangChainAI tested @typesafeai jev on fixed agent traces. it averaged 0.44s and $0.00035 per judgment, with 92-913x lower score variance than the llm judges they tested.
small benchmark. big architecture clue.
Related builds