VERIFYSearch & retrieval
Jev for RAG Pipeline Evaluation

Shaun@smc_shaun
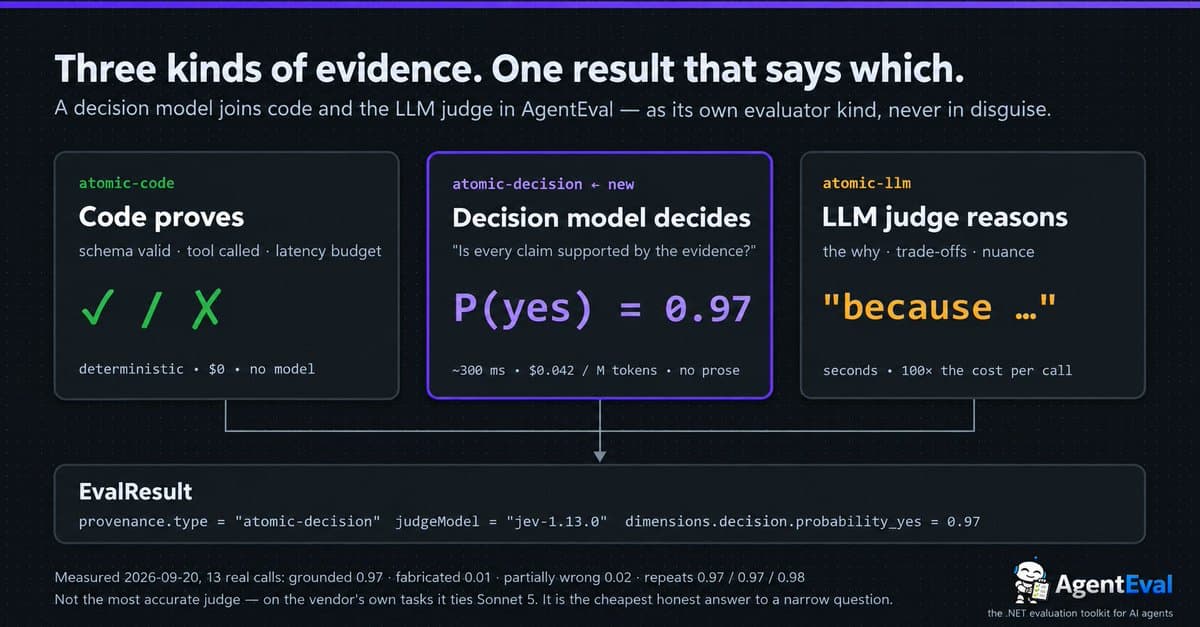
This project explores the use of Jev as a judge layer within a Retrieval Augmented Generation (RAG) pipeline to assess retrieved chunks for relevance, perform citation checks on LLM answers, and escalate low-confidence responses to an LLM or human.
Anyone using @typesafeai's Jev in a RAG pipeline yet?
I'm testing it as a judge layer: Noul per retrieved chunk for relevance, citation check on the LLM answer, low confidence escalates to the LLM or a human.
What thresholds and patterns are working for you?
Related builds
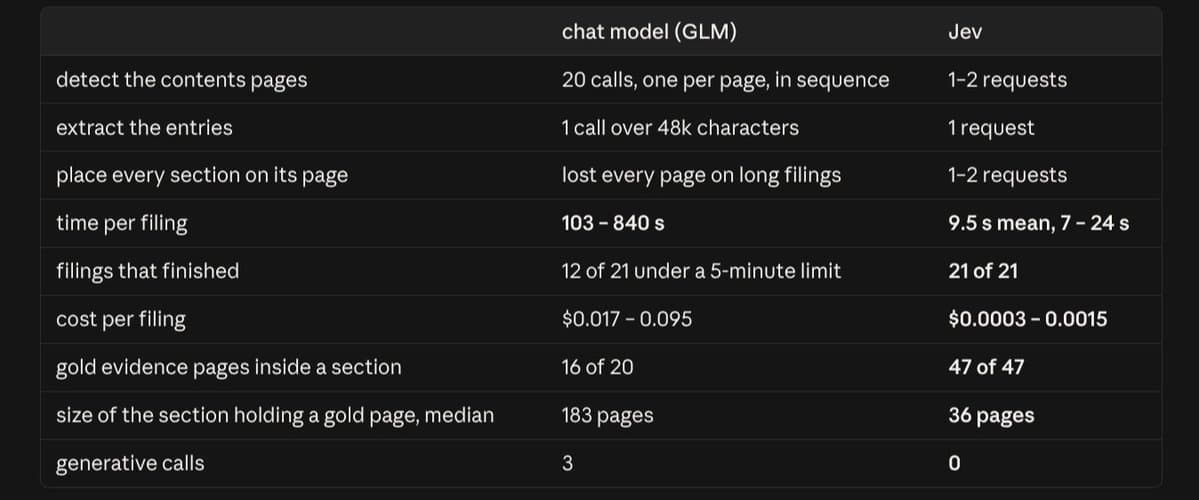
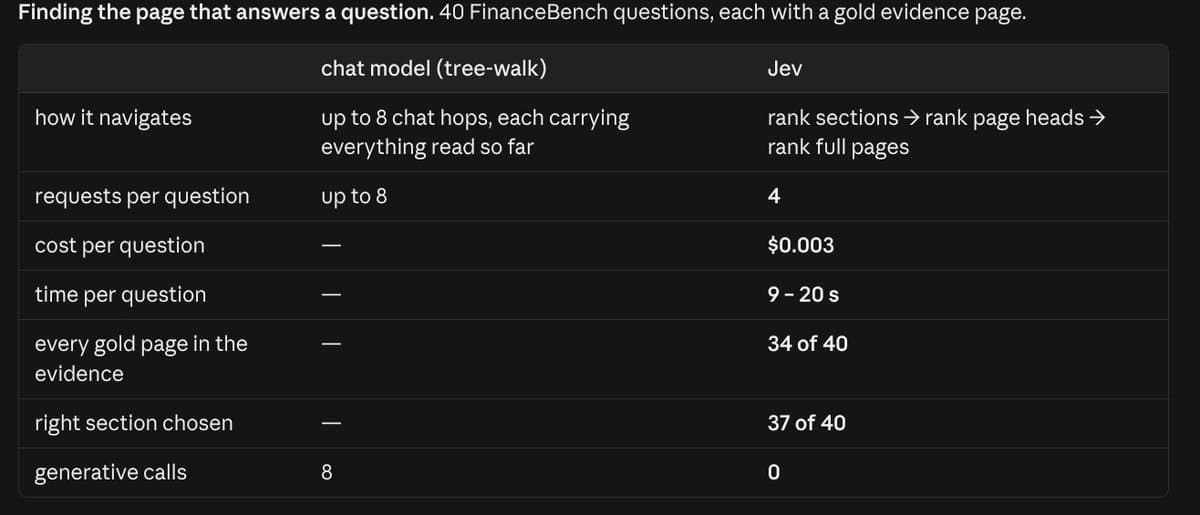
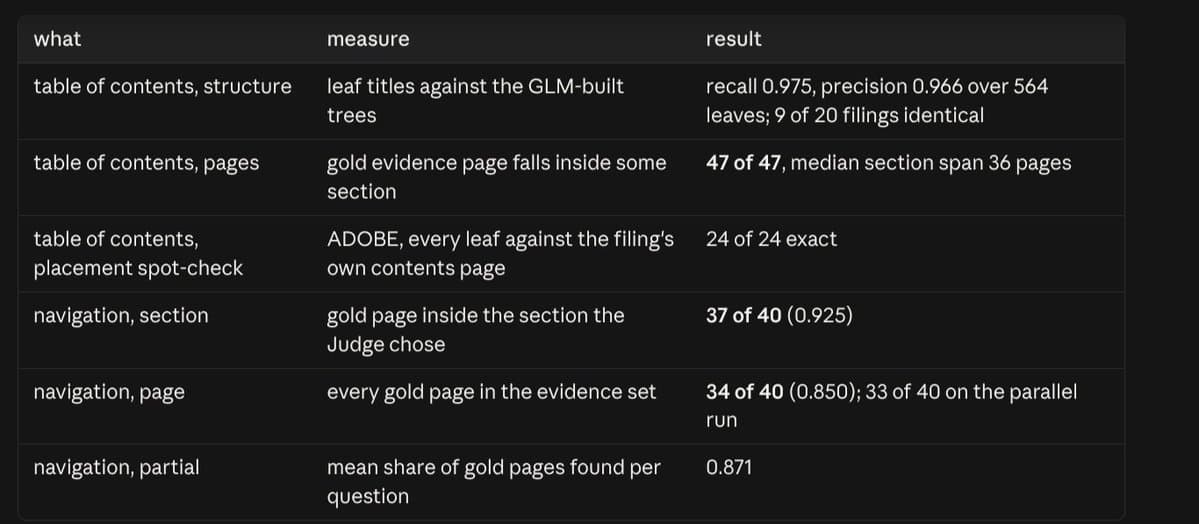
Vectorless RAG with Jev
This project introduces a novel approach to Retrieval Augmented Generation (RAG) that replaces traditional embedding methods with a structured, table-of-contents-based navigation system, significantly improving speed and reducing costs by offloading non-generative tasks to Jev.