GATEDevtools & code
TypeSafe Jev Model and Gemini Integration Test

Usher | عاشر@IranUsher
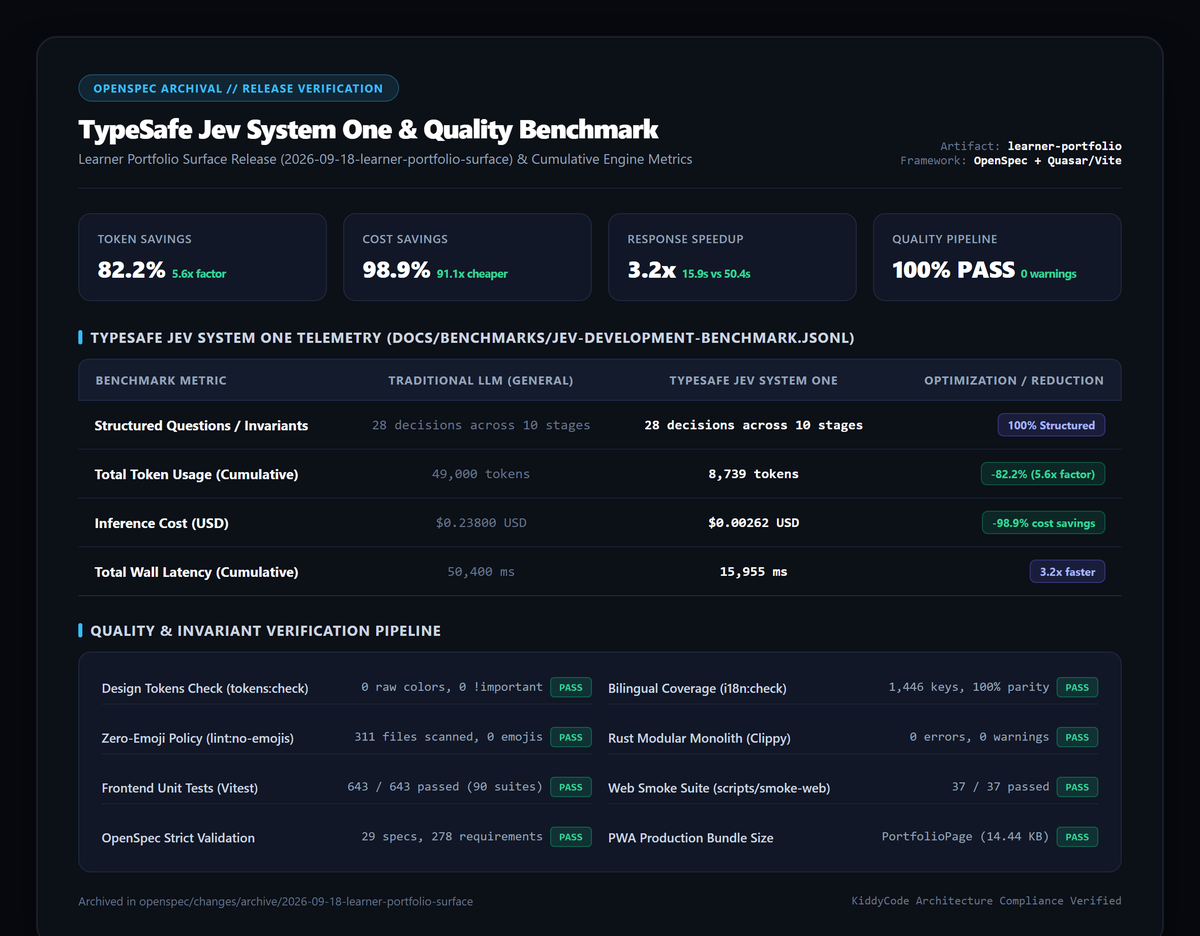
This project tested the TypeSafe Jev model alongside Gemini across 10 development stages, observing significant reductions in token footprint, latency, and evaluation cost.
Not claiming this is a massive enterprise benchmark—just a quick, practical test we ran today in under a single day of development:
We tested TypeSafe's Jev model alongside Gemini across 10 development stages (28 structured decisions covering sandbox security postures, search ranking, and accessibility gates).
In less than 7 hours of testing today, here is what we observed:
Token footprint: Dropped from 49,000 to 8,739 tokens (~82% reduction). The real benefit was context window hygiene: Gemini's prompt context remained entirely dedicated to code synthesis and debugging instead of evaluation scaffolding.
Latency: 15.9s total wall-clock time vs 50.4s on multi-stage LLM prompts (~3x faster).
Evaluation cost: Went from ~$0.24 to under a third of a cent ($0.0026).
Just a small, real-world test, but it clearly demonstrated how pairing fast System 1 probability models with general LLMs like Gemini prevents context bloat in agentic coding workflows.
@typesafeai
#SoftwareEngineering #AI #DeveloperTools #BuildInPublic #Gemini #TypeSafeAI #RustLang