SCOREAI infra
Jev Model Performance Evaluation

Kyle Wild@dorkitude
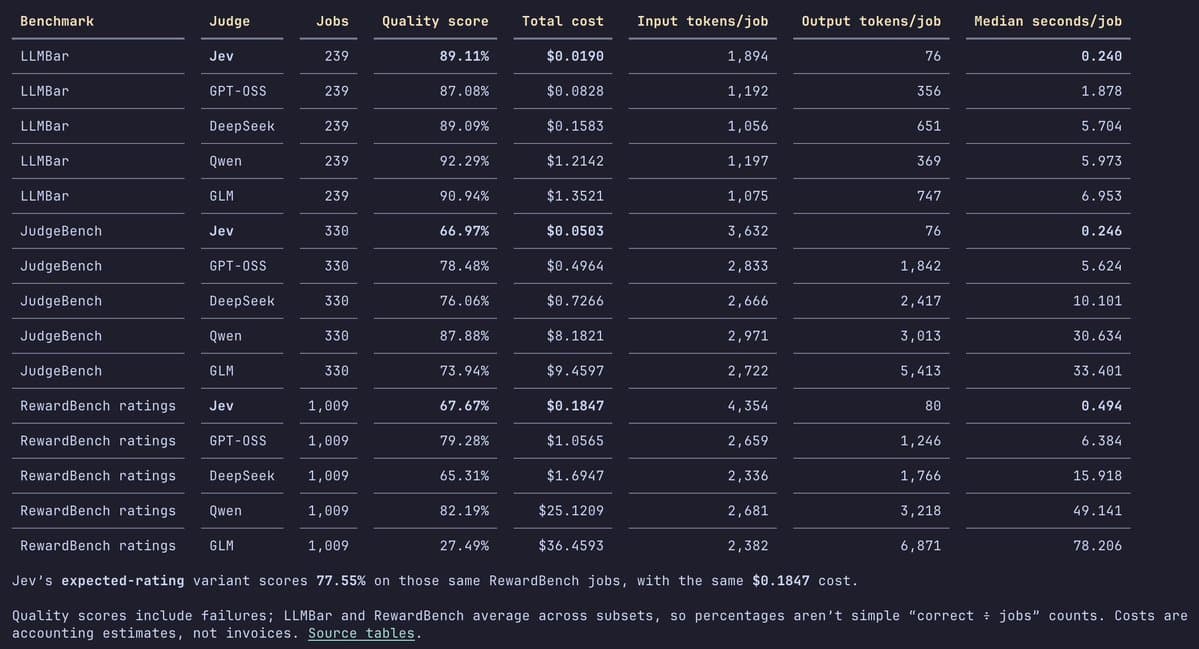
This project evaluates the performance of the new Jev model against several LLMs across multiple benchmarks, highlighting its competitive pricing and speed.
Early results from my all-nighter experiments with the new (non-LLM, "System One" class) Jev model from @typesafeai
I ran LLMBar, JudgeBench, and RewardBench comparing Jev (hosted by Typesafe) to LLMs GPT-OSS, Deepseek flash, and GLM flash (hosted by @FireworksAI_HQ)
as you can see, Jev's nearest competitor in these evals (which are designed to be hard, and may be a little too tough for both) is GPT-OSS.
GPT-OSS has higher quality on most tests across the board (but lower on the easiest one, LLMBar), at "only" 5-6x the price of Jev. it's also ~15x slower.
GLM and Qwen are 50-100x more expensive for similar quality scores on the easiest one.
I think Jev is going to find its way into a _LOT_ of production workloads beyond evals... but evals alone would give it a pretty freaking large market.
I'm salivating and I can't wait for it to be enterprise ready!