FILTERDevtools & code
sgrep: Semantic Grep with Jev

lagnajit.@m_lagnajit09
sgrep is a semantic grep tool that uses Jev to reduce the amount of code an LLM needs to process for a given query, leading to significant reductions in token count, lines of code read, and latency.
Got an early access to @typesafeai Jev and tried it with something real:
I built sgrep — semantic grep powered by Jev.
The idea:
(improve context engineering)
semantic locate → read only what's relevant → give it to the LLM
Instead of making Claude read large portions of a repo just to find the code relevant to a question.
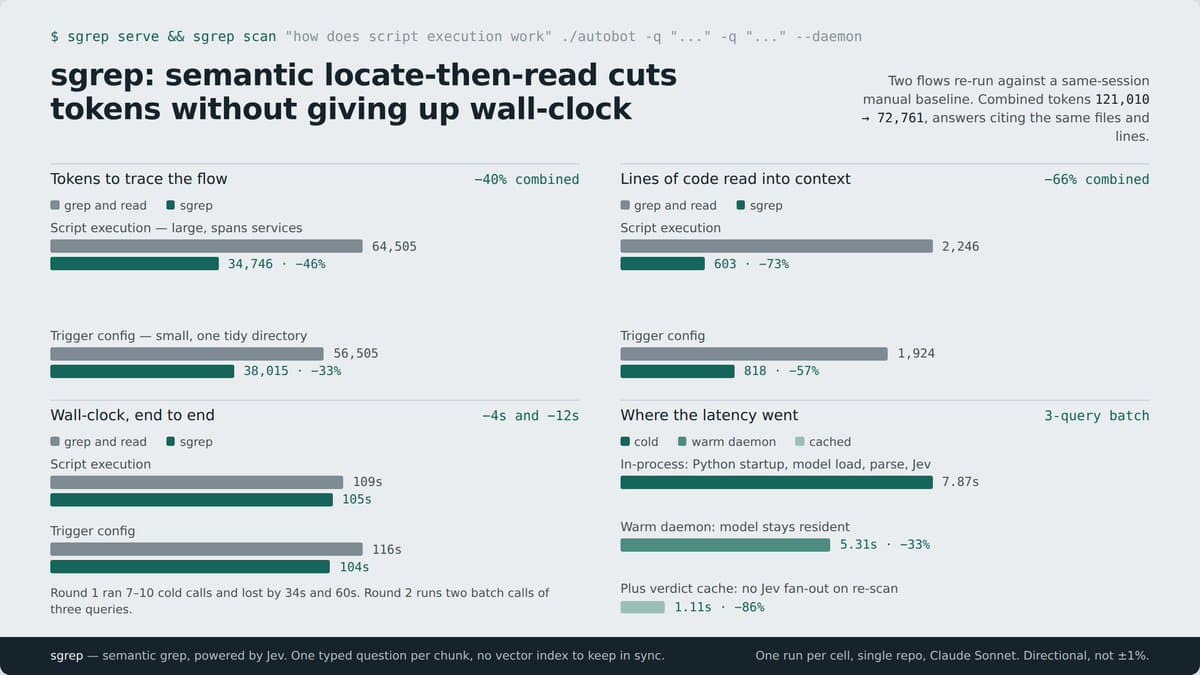
I ran both approaches against the same repo, same session, and same queries.
The results:
121,010 → 72,761 tokens
(~40% reduction)
4,170 → 1,421 lines of code read
(~66% reduction)
And the answers still cited the same files and lines.
The latency was interesting too.
With Jev's model kept warm:
7.87s → 5.31s
And on a re-scan with verdict caching:
1.11s
The bigger takeaway for me isn't just token savings.
It's a different way to think about context engineering:
Don't make the LLM search the entire world.
Use a fast decision layer to determine what should enter the context and what to ignore. More importantly, Claude was able to locate the relevant code much faster.
LLMs can spend their compute on reasoning.
Jev can help spend it on decision and selection.
That's what I wanted to test with sgrep.
Related builds