CHOOSEAgents & automation
𝗜 𝗿𝗮𝗰𝗲𝗱 𝗝𝗲𝘃 𝗮𝗴𝗮𝗶𝗻𝘀𝘁 𝗖𝗹𝗮𝘂𝗱𝗲 𝗢𝗽𝘂𝘀, 𝗛𝗮𝗶𝗸𝘂 𝟰.𝟱 𝗮𝗻𝗱 𝗚𝗣𝗧-𝟱.𝟰

Shen Sean Chen@ShenSeanChen
 22:29
𝗜 𝗿𝗮𝗰𝗲𝗱 𝗝𝗲𝘃 𝗮𝗴𝗮𝗶𝗻𝘀𝘁 𝗖𝗹𝗮𝘂𝗱𝗲 𝗢𝗽𝘂𝘀, 𝗛𝗮𝗶𝗸𝘂 𝟰.𝟱 𝗮𝗻𝗱 𝗚𝗣𝗧-𝟱.𝟰 𝗠𝗶𝗻𝗶, 𝗮𝗻𝗱 𝗯𝘂𝗶𝗹𝘁 𝘁𝗵𝗲 𝗷𝘂𝗱𝗴𝗺𝗲𝗻𝘁 𝗮𝗿𝗲𝗻𝗮 𝘁𝗼 𝗱𝗼 𝗶𝘁.
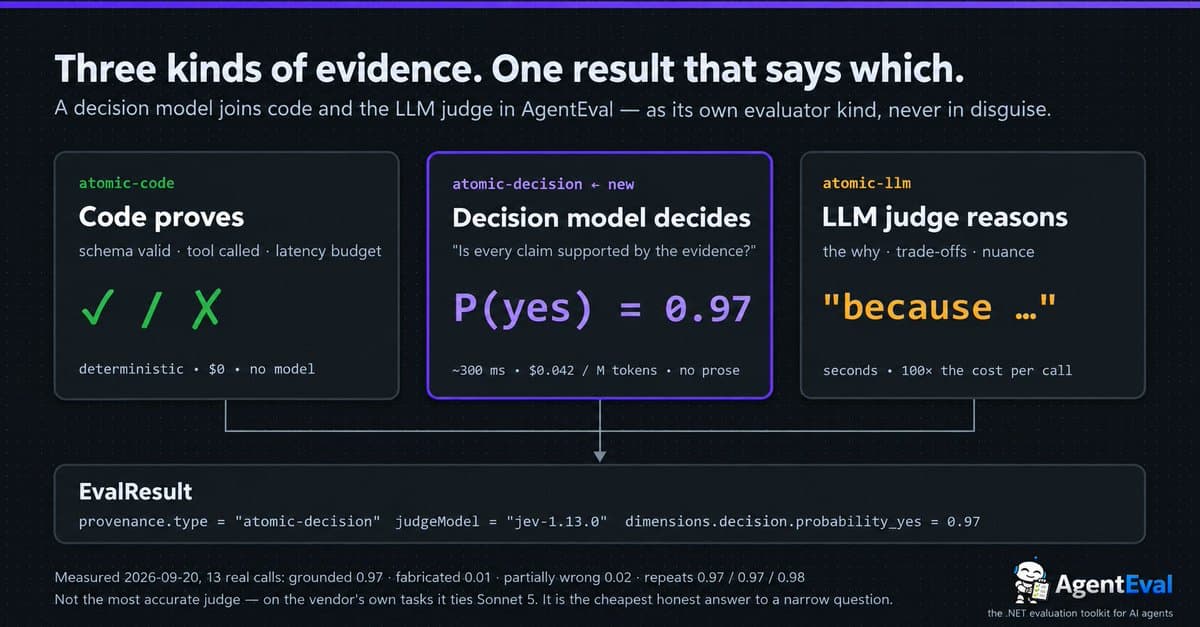
Jev is @typesafeai's System One model, and it does something no chatbot does: it never talks to you. JSON in, JSON out, a probability on every answer.
I drew System 1 and System 2 out on the whiteboard first, step by step, then put all four models on the same 15 human-labelled questions inside my own dashboard.
🌟 Github Repo (1.8k): github.com/ShenSeanChen/waku-agent
💻 Portable memory: waku.one
☕ Join our community: seanchen.io
Opus scored highest. It also took 10x longer and cost 146x more than Jev to get one extra answer right out of 15.
Accuracy stops being the deciding number somewhere, and for fast judgment calls I think we're already past it.
Picking a side is easy. Ranking how much is hard. Turns out that's true of models for the same reason it's true of us.
Watch it, save it, let me know what you think. 📕
You Can Build Anything. You Can Learn Anything. 💪