SCOREAgents & automation
Jev as an Agent Judge Benchmark

AI Horizon Blog@AIHorizonBlog
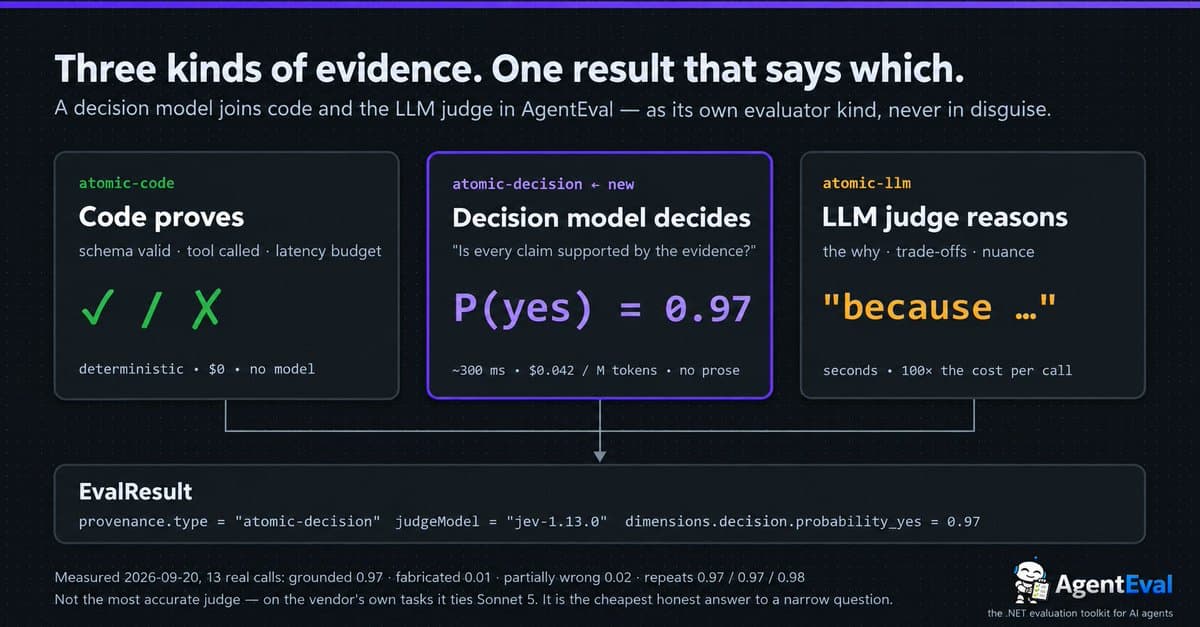
LangChain evaluated Jev, a model that provides typed answers and probabilities, as an agent judge, finding it superior in accuracy and cost compared to LLM judges like Claude and GPT-5.6.
TakeEach judge scored the same five weather-agent responses 100 times against a human-reviewed ground truth.
Pattern✦ Agent trace evaluation with typed judges
No. 2 in today's top 5: LangChain tests Jev as an agent judge — it beats Claude and GPT-5.6 on accuracy and cost.
What happened: LangChain used LangSmith to pit TypeSafe's Jev, a model that returns typed answers and probabilities instead of generated text, against three LLM judges — GPT-5.6 Luna, GPT-5.6 Terra, and Claude Sonnet 4.6 — as agent evaluators. Each judge scored the same five weather-agent responses 100 times against a human-reviewed ground truth. Jev matched the human oracle 100% of the time at $0.00035 and 0.44 seconds per call, versus 80.0% accuracy and $28.17 total for the Claude judge run on the same workload.
Why it matters for FDEs: LLM-as-judge pipelines are usually rationed for cost and re-run instability, and a judge this cheap and this consistent means you can score every trace on every deploy instead of sampling.
See the numbers:
ai-horizon.blog/post/2026-09-21/langchain-
#Evals #LLMAsJudge #AgentEvaluation #ForwardDeployedEngineering
Related builds