SCOREAgents & automation
Jev System One Model Evaluation

Read the Diff@read__the__diff
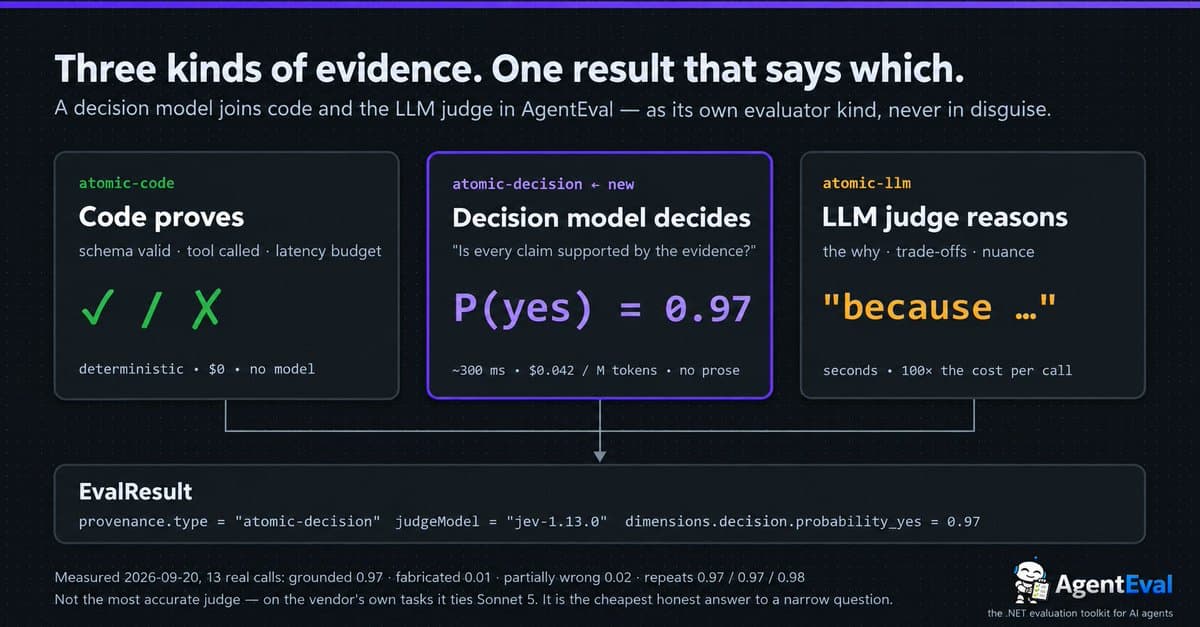
This project evaluates Jev, a System One model, against standard LLM judges on accuracy, repeatability, latency, and cost, exploring the trade-off between fast, pattern-matching reasoning and slow, step-by-step generation for agent evaluation.
Pattern↑ Agent trace evaluation with typed judges
You evaluate your agents with another LLM and you assume the judge is consistent. LangChain tested Jev, a System One model, against standard LLM judges on accuracy, repeatability, latency, and cost.
System One models are built for fast, pattern-matching reasoning rather than slow chain-of-thought generation. The idea is that evaluation does not always need a heavyweight reasoning model, a cheaper and faster one may be enough. LangChain measured whether that tradeoff holds on real agent outputs, comparing Jev to judges that reason step by step.
The result worth watching is repeatability: a judge that scores the same run differently on two passes is noise, not a metric. If a cheaper model matches an expensive one on consistency while cutting latency and cost, the expensive judge becomes a default, not a requirement.
Related builds